Showing posts with label programming. Show all posts

Saturday, January 30, 2016

Introducing Mappy

During my nice little break last week I figured, why not? I'll make my toy programing language more real! The result is a functional programming language that is similar to Lisp, except maps (aka dictionaries, aka HashMaps, aka Hashes) are the core primitive, rather than lists.

You're probably thinking to yourself, "what's the point in yet another Lisp-like language?" Well, that's a great question! Mappy's really a breakable toy for my amusement (i.e. in its current state, Mappy's definitely not ready for production). That being said, here are some interesting design choices in the language
  • I decided to go with maps rather than lists, because maps are more closely related to functions
  • Keeping expressions simple and singular (a la Lisp) makes parsing and grammar rules trivial
  • (Bias alert) Haskell is an amazing language in which to implement compilers
  • I didn't want to implement if as a core primitive, so I had to choose between non-strictness and auto-closure function arguments (the latter won for simplicity reasons)
  • Parsec and QuickCheck can really save you when you're trying to keep complex rules consistent (e.g. parsing)
  • Github issues and milestones are an excellent way to break a problem into small chunks and really focus
  • Implementing IO as a map has had constraining effects (no pun intended) that are similar to the IO monad
If you're interested in contributing, have a peek at the issues or feel free to play with it, see the README, and/or file some issues!

Sunday, November 15, 2015

Write a File in Idris

Although Idris' documentation seems better than 99% of opensource projects out there, I couldn't easily find the steps necessary to write a file. After recalling that Brian McKenna wrote his blog in Idris, I figured he would have a nice example of how to write a file and I was right! This post is heavily ripped from his work. The actual code (taken from the Main file of Brain's code generator) looks like
writeFile : String -> String -> IO ()
writeFile f s = do
  f <- openFile f Write
  fwrite f s
  closeFile f
Pretty straight forward. It takes a file name and the content to write, opens a handle, writes the contents to that file then closes it. Now, I had found and written code like this in Idris' docs, but couldn't get it to compile. The trick was to tell Idris to compile and include the effects package, like so
idris -p effects Main.idr -o my_program
Thanks Brian!

Sunday, October 25, 2015

Trie in Haskell

Lately I've been playing around with Haskell. As an exercise, I decided to partially implement a Trie. I ignored the various implementations out there, including Data.Trie and the one linked on Wikipedia. Instead I focused on iterating on a Trie from scratch, and I found the results to be pretty interesting, so I'm sharing them here.

My real goal with this exercise was to implement "member", "insert" and a sorted "toList" and to do so somewhat generically. This interface turns out to be more similar to a Set than say a Map, because there aren't values associated with members. I used [a] to represent a member of the Trie a which, in retrospect, looks like a Monoid. Well, anyways, my first structure came out looking like

data Trie a =
  RootNode [TrieNode a]
  deriving Show

data TrieNode a =
  Leaf a
  | SpineEnd a [TrieNode a]
  | Spine a [TrieNode a]
  deriving Show

In this modeling, Leaf a indicated the end of a member at a leaf, SpineEnd a [TrieNode a] indicated an end on a spine, Spine a [TrieNode a] was a non-ending spine, and well RootNode [TrieNode a] indicated the root. At first glance, I really liked this model. After implementing the Trie, however, I found the structure less than desirable for a few reasons
  • Since "edges" are a list, a fair amount of boilerplate traversal code was necessary to implement the operations
  • Although at first I liked keeping RootNode separate, but later I realized it was inhibiting me from inserting the empty list
  • Turns out that Leaf a is totally redundant with SpineEnd a []
I'm much more pleased with the second structure I came up with
import qualified Data.Map as M

type TrieEdges a = M.Map a (Trie a)

data Trie a =
  Node { edges :: TrieEdges a }
  | EndNode { edges :: TrieEdges a }
  deriving (Show, Eq)

empty :: Trie a
empty = Node M.empty
Not only does this design have fewer parts than the other, but it yielded a simpler implementation. Here's the code for insert
insert :: Ord a => [a] -> Trie a -> Trie a
insert [] n = EndNode $ edges n
insert vs (Node m) = Node $ insertBelow vs m
insert vs (EndNode m) = EndNode $ insertBelow vs m

insertBelow (v:vs) m = M.insert v (insert vs child) m
  where child = M.findWithDefault empty v m
I believe it's pretty straightforward. The only real tricks were safely creating edges where none existed (which is the main purpose of insertBelow) and ensuring that the node at the end of a member is an EndNode. The member function turned out even nicer
member :: Ord a => [a] -> Trie a -> Bool
member [] (EndNode _) = True
member [] (Node _) = False
member (v:vs) n = maybe False (member vs) . M.lookup v $ edges n
Getting an in-order toList was a little bit tricker but, thanks to the useful functions in Data.Map it was quite doable
toList :: Trie a -> [[a]]
toList = go []
  where
  go acc (Node m) = continue acc m
  go acc (EndNode m) = reverse acc:continue acc m

  continue acc = concatMap (\(v, n) -> go (v:acc) n) . M.toList
In conclusion, if you have any comments, improvements or tips to make this better let me know!

Sunday, June 28, 2015

Object Oriented Clojure Example

Inspired by the message passing content in The Structure and Interpretation of Computer Programs (SICP), I decided to try my hand at object oriented-style programming in Clojure. Here's what I came up with, using the traditional bank account example

(defn make-account [initial-balance]
  (let [bal (ref initial-balance)
        withdraw (fn [amount]
                   (dosync (alter bal #(- % amount))))
        deposit (fn [amount]
                  (dosync (alter bal (partial + amount))))
        amount (fn []
                 (deref bal))
        reset (fn []
                (dosync (ref-set bal initial-balance)))]
    (fn [meth & args]
      (cond
        (= meth :withdraw) (withdraw (first args))
        (= meth :deposit) (deposit (first args))
        (= meth :amount) (amount)
        (= meth :reset) (reset)))))

Overall, it was a fun little bit of code to write! It has a constructor (make-account), a private variable with mutation (bal) and some messages it responds to (:withdraw, :deposit, :amount and :reset).

Here's an example of it being used
(def account (make-account 1000))
(println (account :amount))
; -> 1000

(account :withdraw 75)
(println (account :amount))
; -> 1925

(account :reset)
(println (account :amount))
; -> 1000

Favor Deletable Code Over Reusable Code

As problem solvers who work primarily in the medium of software, we're sold reusability throughout our careers (and even, likely, in our educations). We're told that if we just think ahead, if we put forth more effort, we can jump to a new plane of abstraction and achieve a solution that will be usable in the future to more quickly and easily solve a similar problem. Although this sounds pretty awesome in theory, I don't buy it in practice.

Arguments against optimizing for reuse

The first real problem I have with premature abstraction (in the hope of reuse) is just that -- it's premature. We'd like to think we know how our system ought to flex in the future, but we just don't. We're not fortune tellers.

We mean well. We build a more general solution than needed to solve a real problem
Our hope, thinking and intention is that future, similar problems will fit nicely into our "framework"
This sounds great, but there's a lot that can go wrong.

Firstly, what happens if our expanded solution doesn't "fully" solve the problem at hand?
Do we rewrite our more general solution to accommodate the actual problem? I find, generally, we don't. Instead we extend and further abstract our large solution to make it encompass the areas we missed. If we do re-write the general solution entirely, the previous general solution was effectively a time sink.

There's a fair amount of regression headache here as well. If I decided to extend my prior abstraction, then I have to do without breaking the parts that partially solved the problem to begin with. Also, assuming I still believed parts of the original abstraction to be valuable to future solutions, I would be required to also keep those from breaking.

 Secondly, there's a question I try to ask myself before I solve future problems: what will happen if this problem is a one-off? I usually have a few different answers to this
  • I will have wasted time building abstractions and tests that weren't actually needed
  • I will have obfuscated the intent of the solution with unnecessary abstraction, forcing future maintainers (myself included) to understand a more general problem than the one actually being solved, and
  • I will have introduced more actual code and tests to maintain (in many codebases this may be a drop in a bucket, but still, more is more)
The third and final consideration I have before thinking about reuse is really a few tightly-related questions, pertaining to reuse itself
  1. If a future problem is solvable by my abstraction, how will developers know to use it?
  2. If a future problem looks like it's solved by my abstraction, but it's actually a different problem, how will other developers know not to use my abstraction?
  3. What happens when a future problem is 90% solved by my abstraction? Is it flexible enough that someone else will be able to extend it to fit that extra 10%, while maintaining its integrity?
In my fairly short exposure to professional software development, I find the answers are something along the lines of
  1. They won't. They'll build another solution, and maybe their own abstraction framework to some degree.
  2. See 1, they probably won't ever see my abstraction or understand it. Although, I have seen a good bit of the "copy the original source, and tweak to fit" pattern applied in response to this question
  3. It won't be flexible enough. They'll build another solution.
Like I said, I'm a novice developer. So if you have solutions to these questions and problems, I'm eager to hear them!

Deletable code

Alright, honesty time. The above words are truly my take on some points made in Greg Young's the art of destroying software talk. At this point, I could spend paragraphs describing the value obtained by having code that, by nature, is easy to delete. But, to do so would be a waste of time when Greg has so well articulated the points. So, with that, I urge you to watch the linked talk, and rip my arguments to shreds in the comments section.

Tuesday, May 19, 2015

Functional Programming Aha! Moments

In the past couple of years, I've dedicated a fair amount of time to closet-functional-programming. Although I haven't gotten an opportunity to use a more purist functional programming language (e.g. not FrameWorkOfTheDay.JS) in my day-to-day day, industry work, I believe some of the values of functional programming have bled into my daily practice, for the better.

Industry aside, I want to share some of the "Aha! moments" I've had while learning about functional programming. These are moments where something just clicked for me; some part of me almost can't help but share them.

Lets Can Be Described by Anonymous Functions

Although "functional programming" is one of those things were if you ask five people for a definition you are likely to get six different definitions, one general consensus seems to hold: assignment should be reduced, minimally scoped or eliminated entirely in functional programming.

The let macro/expression/sugar is basically a means of reducing assignments into minimally scoped, (generally) non-mutative expressions with a set of bindings. Here's a contrived example of what this might look like in Clojure


Here we're saying, let's bind `x` to `35` then `y` to a value calculated from `x`, then we'll use `y` to calculate some result. This entire expression is just that, it's an expression. This `let` is evaluated as a whole, and the result is simply `42`.

So, here comes the first "Aha!" This same kind of scoped assignment can be done through applying anonymous functions! Here's what that looks like for the above example

Basically the pattern here is just, for each bound symbol (in this case `x` and `y`) nest and call an anonymous function, passing the bound value down (`35` and `(- x 14)`)! I found this discovery exceptionally cool because it further emphasized the power of these functional languages: something as simple as anonymous functions can be combined to form powerful abstractions. 

Monadic Bind Is Like Method Chaining

Monads, in general, have provided many an "Aha" for me. They're definitely one of those constructs where, once you get passed the initial "this is slightly out of my comfort zone" feeling, you are ready to embrace an overwhelming amount of power.`bind` (looks like `>>=`) is one of the crucial operations implementable by a monad, it has the following type signature

Ignoring currying and some other subtleties, if I'm thinking in an "object oriented mindset" I might reason about this as follows:
  • `bind` is a function that take 2 arguments
    • a generic wrapper around some type `a`
    • a function which takes some `a` and returns some generic wrapper around type `b` (where `b` may be the same type as `a`)
  • `bind` returns some generic wrapper around type `b`
To me, this sounds exactly like a single call that enables method chaining! Think a la calling `bind` to transform from monad to monad to monad... In my mind, `bind` is an enabling feature, that allows Haskell code to be elegant, expressive and powerful without lacking type safety (see `do` notation).

To visualize how this is kind of like method chaining, observe the following Ruby code

We can imagine these calls (with the exception of `count`) being like a type-not-so-safe version of Haskell's `bind` applied a couple of times (2 to be exact). Here are what the steps might look like
  1. `m a` is a range of `Fixnum` (e.g. `Range Fixnum`)
  2. `map` applies a block that takes the `Range Fixnum` and returns an `Array Fixnum`
  3. `select`, with its block, takes an `Array Fixnum` and returns an `Array Fixnum`
  4. Finally, `count` is simply applied to the `Array Fixnum`

Message Passing (OOP Style) Can Be Achieved via Closures

Disclaimer/Plug: this last "Aha" is shamelessly ripped off from The Structure and Interpretation of Computer Programs (SICP). I am over half way through this book, it is wonderful, please consider showing the authors your support by buying it.

The authors of SICP take the reader through a fantastic journey in which the powers of LISP and functional programming are clearly displayed through examples in the Scheme dialect. One piece of this journey that recently blew my mind was when the authors used closures to define a mutable bank account that responds to different messages. Here's the code (again shamelessly ripped)

What you're seeing here is basically a constructor that builds objects, given a beginning balance, that respond to the `'withdraw` and `'deposit` messages.

Frankly, I don't really know what I can say about this that the authors haven't already said (1) more articulately, (2) more clearly and (3) in a more inspirational manner.

In conclusion, these are just a few of the awesome concepts I've picked up in my pursuit of functional programming. If you have any thoughts on these, or my description of them, don't hesitate to comment.

Thursday, April 9, 2015

OOP Setters Can be Used to Emulate Partial Application

Recently I was asked an awesome question that went something like
How would you do something like high-order functions and partial application in object-oriented programming?
For high-order function my mind immediately jumped to Guava's Function Interface. I said, "hmmmm, let's see, could have some method (maybe called partiallyApply) that took an argument and returned another Function." In retrospect, this may have been overly complex, and a much simpler implementation of Function may work just as well in this case: fluent setters.

Let's look at a contrived, dead-horse-esque example. A partial function that does addition on two arguments.

In Haskell, if I wanted to build such a function, and partially apply it to, let's say 5, I might do the following
add5 = (+) 5

add5 10 -- is 15
In Clojure, this might look like
(def add-5 (partial + 5))

(add-5 10) ; is 15
So, how would I do this using setters? Simple! Here's some Ruby code
class Adder
  def value(first)
    @first = first
    self
  end

  def to(second)
    @second = second
    self
  end

  def add
    @first + @second
  end
end

adder_of_5 = Adder.new.value(5)

adder_of_5.to(10).add # is 15
This code (obviously) has a lot more ceremony wrapped around it, but it does achieve some of the same benefits as partial application (e.g. laziness, partial parameter fulfillment). The point is, if this were Java code, I could easily implement Function and change add to invoke and have a partial function in an object-oriented system.

Sunday, February 1, 2015

LISP Core in Less Than 100 Lines of Haskell

A couple of months ago, I built a LISP core engine in about 100 lines of Haskell code (of course, just for the fun of it). I thoroughly enjoyed the challenge, and with the help of techniques from the awesome Programming Languages MOOC I was taking, I felt ready to take it on. In conclusion, it was truly a fun project and I thought I'd share some things I learned along the way.

LISP's Core Primitives are Easily Implemented Recursively


In the simplest terms, the LISP core engine I built is simply a function that operates, with a specific environment (variable bindings) in mind, on the LISP syntax tree. Because of this I was able to implement primitives like label (aka define) simply with pattern matching and the cons (: in Haskell) operator!

To show how simple these primitives were to define, here's eq? (checks equality)
aux env (AList (Atom "eq?":a:b:_)) =
  if aux env a == aux env b then aTruthyValue else theFalseyValue
Note that aux is the name of the helper function called by the executor.

Haskell Code Can Be Very Elegant


There aren't many languages in which code as elegant as this can be written:
executeText env = execute env.parseMany.tokenize
In my opinion, it doesn't get much more straight forward than this. The dots may throw C-style programmers, but to a Haskell programmer they're pure gold.

Additionally refactoring in Haskell is extremely powerful. Consider the evolution of my bind function (takes names and values and adds them to an environment). It started as this:
bind [] [] env = env
bind (name:names) (value:values) env = bind names values ((name, value):env)
then was transformed to this:
bind names values = (++) $ zip names values
and ended up as:
bind names = (++) . zip names
In Haskell, it seems, there is a function for everything. Honestly, there's probably even one out there that can replace my bind function, I just haven't found it yet!

The Macro System is Pretty Cool


At the moment, the macro system in this LISP is pretty tight. Macros are written in Haskell code (I would like to eventually add support in the language) and are provided with (1) and "eval" which encapsulates the current environment and can run code and (2) a list of the arguments passed to the macro.

All registered macros are simply added to a list, and are thus loosely coupled to the actual core engine (but tightly coupled to the AST since they are essentially generating new portions of it).

Here's an example of how I defined if, in terms of the cond primitive:
structuralMacros = [(
  "if", \_ (p:a:b:_) -> AList [Atom "cond", p, a, Atom "1", b]),
  ...]

Parting Words


If you're interested in the full code, it's on github. Also the project has a REPL whose build step is at the bottom of "README.md."

Saturday, January 31, 2015

Hash Table (Map) Built In Python

Lately, I've been studying up on my data structures and algorithms. I decided it would be fun to implement a HashMap (the map abstract data type). I decided to rely on Python's idiomatic __hash__ function, and use linear probing as the collision resolution mechanism. In the process of building this, I learned a few things and I would like to share them.

Deletion is the Hardest Part


Overall the data structure was not very difficult to build. Well, except for deletion. It's not as simple as shifting all elements back (overwriting the deleted). Instead, I had to flag the item as being "deleted". This wasn't that difficult, however, maintaining quick-access sizing on the data structure was complected by it.

In the end, I had to maintain two states: one that programmers who called __len__ would see and the actual count of stored elements (being actual plus deleted).

Linear Probing is Not as Hard


My "find index" method, boiled down to just
    def __locate_index(self, key):
        i = hash(key) % self.capacity()

        while self.__values[i] and self.__values[i][0] != key:
            i = (i + 1) % self.capacity()

        return i
Where each value is just a tuple where elements 0 and 1 are the key and its value, respectively.

Everything Else is Just Bookkeeping


In the end, the code wasn't too difficult. In the end, the class had a lot more state than I would've liked, however, "getting it right" wasn't that difficult. As always, I hope I'm not missing any edge cases with my tests.

As usual, the code is on github and I'm open to any suggestions or thoughts.

Wednesday, November 19, 2014

Just-For-Fun Clojure Spec DSL

TL; DR Clojure is hip for DSLs

Just for the fun of it, I've been playing around with Clojure, building a for-fun spec testing DSL (kind of like RSpec). So far, I must say, Clojure is working awesomely!

Since functions are the first-class citizen (and arguably the highest-class), it seemed natural to start off by defining ways to test them and simple values because, technically, if you can test a value, you can test the application of a function. However, testing return-value-only is not the spec testing way. Things should be descriptive.

So, here are a few examples of my spec testing DSL in action:
(describe 42
  (it > 31))

(describe +
  (when-applied-to 1 2 3 4
    (it = 10)))

The DSL is truly _that_ simple! Sure, these are simple tests, and yes, there's no nice documentation-esque output (yet). But, I just wanted to show how dead simple this DSL is at the moment.

To do the same operation in RSpec, I believe I would have to do something like:
describe 42 do
  subject { 42 }

  it { is_expected.to be > 42 }
end

describe '#sum' do
  subject { sum(*args) }

  context 'when applied to 1, 2, 3 and 4' do
    let(:args) { [1, 2, 3, 4] }

    it { is_expected.to be 10 }
  end
end

This isn't terrible, and I in absolutely no way claim this little DSL is as powerful as RSpec, but it is pretty neat, eh? Also, not to mention, the DSL is about 21 lines at this moment (whoot whoot for macros!)

Pure TDD: A JavaScript Example

The other day I took some time to practice TDD, in JavaScript. I chose a problem at random from cyber-dojo and worked my way through, as by-the-book (following Red->Green->Refactor) as I could.

Not only did I finish this exercise, but I committed each step of the process to github.

So, if you're interested in reading through an example as-pure-as-I-can-at-the-moment-TDD-session, start with this commit (I'd recommend a tool like `gitg` so that you can step through the commits easily).

Some Notes

  • The problem took me 12 Red->Green->Refactor cycles where I kept divided up a lot of the refactors into smaller steps (to keep the commits sensible).
  • At some points the algorithm got kind of bloated, but overall patterns did emerge and were easy to generalize.

Sunday, July 20, 2014

Ruby Metaprogramming: class_eval

Lately I've been looking into ways of DRY-ing up ruby classes. One of the first, and perhaps most scarily powerful, is the class_eval method.

What does it do?

class_eval takes in a block or a string and executes it at the class-level. It's that simple!

Is it useful?

Yeah, it's scary useful. Here's an example where I define a bunch of similar methods on a class:

class Person
  ['age', 'name', 'favorite_color'].each do |attribute|
    ['with', 'and'].each do |prefix|
      class_eval %Q(
        def #{prefix}_#{attribute}(value)
          @#{attribute} = value
          self
        end
      )
    end
  end

  def to_s
    "Name: #@name, Age: #@age, Favorite Color: #@favorite_color"
  end
end

me = Person.new.
  with_name('Michael').
  and_age(22).
  and_favorite_color('Blue')

puts me.to_s # => Name: Michael, Age: 22, Favorite Color: Blue

This short little example used class_eval to define 6 methods on the person class: with_age, and_age, with_name, and_name, with_favorite_color and and_favorite_color! Pretty cool, huh?

Thursday, July 3, 2014

Go(lang): Use a Function to Modify a struct via Reflection

I just started learning Go recently and I must say, it's been a lot of fun. The first real difficulty I've had with the language has been trying to use reflection to set a field on a struct, inside of a function. I found some decent examples, but none that were quite fitting, so I thought I'd share my solution here.

So, just for the fun of it, let's say we have a struct that we know will "always" have a field Brewery:

type Beer struct {
    Brewery string
}

Note that Brewery is public (sorry for the term, my non-Go experience is showing).

Now let's say we want to create a function that always sets the Brewery to "Dogfish Head", but we want it to operate on the general interface and use reflection (for whatever reason):
import "reflect"

func breweryToDFH(thing interface{}) {
    reflect.ValueOf(thing).
        Elem().
        FieldByName("Brewery").
        SetString("Dogfish Head")
}

Finally, to call it, a pointer must be used, e.g.

beer := Beer{}
breweryToDFH(&beer)

And that's all! As one coming from the dynamicity of Ruby, this seems kind of roundabout. So if you know a way to simplify, please feel free to comment. Also, there is a good deal of error handling that should be done here, so for that, I will defer to a stackoverflow post.

Happy "Go-ing"!

Friday, May 23, 2014

What Is A Monad?

Being a hobbyist Haskell programmer, I have heard the term "monad" a lot. In my experience playing with Haskell I have used monads plenty of times, however, it was not until recently that I have come to a digestible understanding of what they really are.

Think Method Chaining

Some of the prominent phrases which I hear being used to describe monads are "they're ways to fake state" and "they are really just a form of method chaining." Although, in my (perhaps nieve) understanding of monads, both of these statements are true, the latter has been far more useful in helping me arrive at a useful understanding of "the m word." So I encourage anyone who may be struggling with the definition of a monad to do the same: think method chaining.

Method Chaining You Say?

Yes method chaining. In the object oriented world this may mean something like this:

someObject.someMethod(1)
          .otherMethod("Pizza")
          .finalMethod()
So, in OOP, the objects returned by each of these methods would encapsulate state. Now, in Haskell, there is not really a concept of state, things are what they are. The sequential mutilation of objects is not something Haskell supports naturally, so it uses the monad as a slick way to sort of "fake state."

What It Looks Like

Disclaimer: this is my current understand of Haskellian monads, and not the similar but slightly different, mathematically definition of monads

To build a monad, two main functions are necessary as well as a monadic type. First I'll discuss a monadic type.

Monadic Type

A monad's type can be whatever it needs to be. Perhaps one of the most famous ones in the Haskell world it the Maybe monad, which is defined simply as:

data Maybe a = Nothing | Just a
Maybe is one of the most beautiful aspects of Haskell. It is very similar to null or nil in other languages, but what makes it different is the fact that (as I understand it) in Haskell's pure, functional model, Maybe cannot go unhandled or pop up in unexpected places. In my mind, it is a kind of a neat and precise example of a monadic type.

The return Function

Another thing a monad needs is a return function whose signature looks like:

return :: a -> m a
return is simply a function whose purpose is to construct the monadic type. Pretty simple, eh? So for Maybe, this might be as simple as:
return n = Just n

The Bind Function

The other function needed by a monad, the function that truly brings out the magic, is the bind function which is usually denoted as (>>=) in the Haskell world. In the OOP example above, the bind function is kind of like the periods in between the different calls, but oh so much more magical. Bind's signature looks like:

(>>=) :: m a -> (a -> m b) -> m b
So, let's break this down.

The first thing that bind takes is a monadic type. So, this could be something as simple as Just 5 or whatever monadic type you are operating on. The second parameter is a function that takes the type boxed by the first parameter (the monadic type) and returns a monadic type boxing b (which could be the same type as a but by no means must be). In the end, bind returns another monadic type, as returned by the middle parameter.

All in all, this seems like a lot to swallow, and, uh, what does this have to do with method chaining or our return function?

Remember, bind is really one of those strange infix operators, so if I may make some simplifications, it kind of looks like:

a thing >>= function that returns another thing
In this simplification, "thing" is substituted for "monadic type" to make bind easier to swallow. The point is, all this whole mess does is return another monadic type! So, there's nothing keeping me from implementing another bind operator (or reusing the same one, if applicable) like such:
a thing >>= function that returns another thing >>= function that returns yet another thing ...
See what I mean about this being like the "period between" in that above OOP example? All bind really does is take some value (wrapped in a monad) and apply some function to it, and re-wrap the output!

return is pretty cool because a lot of the time it comes at the end of all the binding (wow, a return at the end? Sounds like some other paradigms out there). return is really the end game, the termination of the "chaining."

Parting Words

In conclusion, I hope I have shed some light on what can be a very difficult topic to understand. If you would like to learn more, the Haskell community has a great article on monads also there are some really awesome answers to the question of "what is a monad" on SO.

Wednesday, May 7, 2014

Why I Dig RSpec

I've been using RSpec a fair amount lately, so I thought I'd talk about some of its features I really dig.

The rspec -f d command

If contexts and describes are favored over loaded setup and it blocks that do too much, you can get some really nice, verbose output from this command.

For example, suppose I have some specs describing a #wear_hat? method of a SimpleDecisions class. My rspec -f d output might look something like the following:

SimpleDecisions
  #wear_hat?
    when I am a vampire
      and it's sunny out
        returns true
      and it's night time
        returns false
    when I am at a home baseball game
      returns true
    when I am at an away baseball game
      and my hat is for my home team
        returns false

Pretty nice, huh? The specs almost match what we would expect the structure of the implementation to be!

Template specs

There's a lot of debate out there about whether test code should be DRY. Some say it shouldn't and that tests should flow and provide context. Others assert (no pun intended) that tests should be maintainable and, therefore, just as clean as (or cleaner than) production code. Template specs meet somewhere in the middle. They can replace many repeated tests at the (slight) expense of maintainability by looping through values and outcomes. For example, a template spec on an absolute value method might look like:

describe Math do

  describe '.abs' do
    [
      [42, 42],
      [0, 0],
      [-42, 42]
    ].each do |given_number, expected_number|

      context "given #{given_number}" do
       subject { described_class.abs(given_number) } 

       it { should be(expected_number) }
      end

    end
  end

end

In my mind, templates are nice when testing a pure function or when there are multiple, similar tests that can be aggregated.

Argument matchers

These are very cool. For example, say I want to test that an error is logged in a certain case, and I don't care about the specific error text, rather I just want the message to be some String. I could write something like this:

  # ...
  it 'logs an error' do
    ErrorLogger.should_receive(:write).with(kind_of(String))
    # cause error
  end
  # ...

This is a fairly trivial example, but these things are powerful. For a further example, presume ErrorLogger.write actually takes two parameters but I don't care about the second. The line would then become ErrorLogger.should_receive(:write).with(kind_of(String), anything).

Natural decoupling

By providing methods like subject and described_class and providing mechanisms to easily redefine the former, RSpec decouples the specs from things like the name of the class under test or the method being tested. For example, in my above absolute value example, if I changed the class from Math to MathUtils then, assuming everywhere below I referenced Math as described_class, I would only have to rename at the top of the file. One change in the production code would merit one change in the tests. Perfect!

Conclusion

Well, I hope I've expressed some of my favorite things about RSpec. If you would like to see any of my specs, they shouldn't be hard to find in my ruby repositories on github. If you have any comments on these points, or anything you really like about RSpec (or dislike for that matter) I'd love to hear your comments.

Tuesday, April 1, 2014

Software Engineering Lessons from Adventure Time

For the past year or so, I've really enjoyed the show Adventure Time. At first glance it seems like a wacky (very wacky) kids show. Eventually, after watching a few episodes, I found myself hooked and haven't strayed to another cartoon since.

Perhaps my enjoyment is generational (being a 90's kid and all) or perhaps the show transcends generational barriers. I truly don't know. All I know is that it's a truly enjoyable show filled with lessons about life, friendship and adventure.

Being one who enjoys software engineering, I will do my best to apply some of the themes found in Adventure Time to common themes of software development. So, here goes...

Don't Make an "Everything Burrito"


In the above photo, take from the episode "Conquest of Cuteness," we see Jake burying "everything burrito" (a burrito containing, well, everything). This made me think. Sometimes, when we write code, we want to make a huge system to solve a small problem, we want to use a crane to crush a fly.

Whether it's intentional or accidental, we have the best intentions. We know our abilities -- we can create truly amazing things. However, we need to keep the YAGNI principle in mind. Many times, our extra functionality becomes, simply, superfluous. We end up building software that will never be used and we have to bury it, similarly to Jake burying everything burrito.

You Have to Fail Before You Can Succeed

The above meme-d line, "Sucking at something is the first step to becoming sorta good at something" rings absolutely true for software engineering (as well as many other disciplines, I am sure). In many ways, software engineering is all about learning! In order to stay up-to-date, we must learn new tools, technologies, languages, and we must do so continuously!

Sometimes learning new things can be daunting. We must realize, as Jake points out, that sucking is the first step to becoming awesome! We will all fail at first, but as we struggle and work, we will persevere and we will grown in knowledge and wisdom.

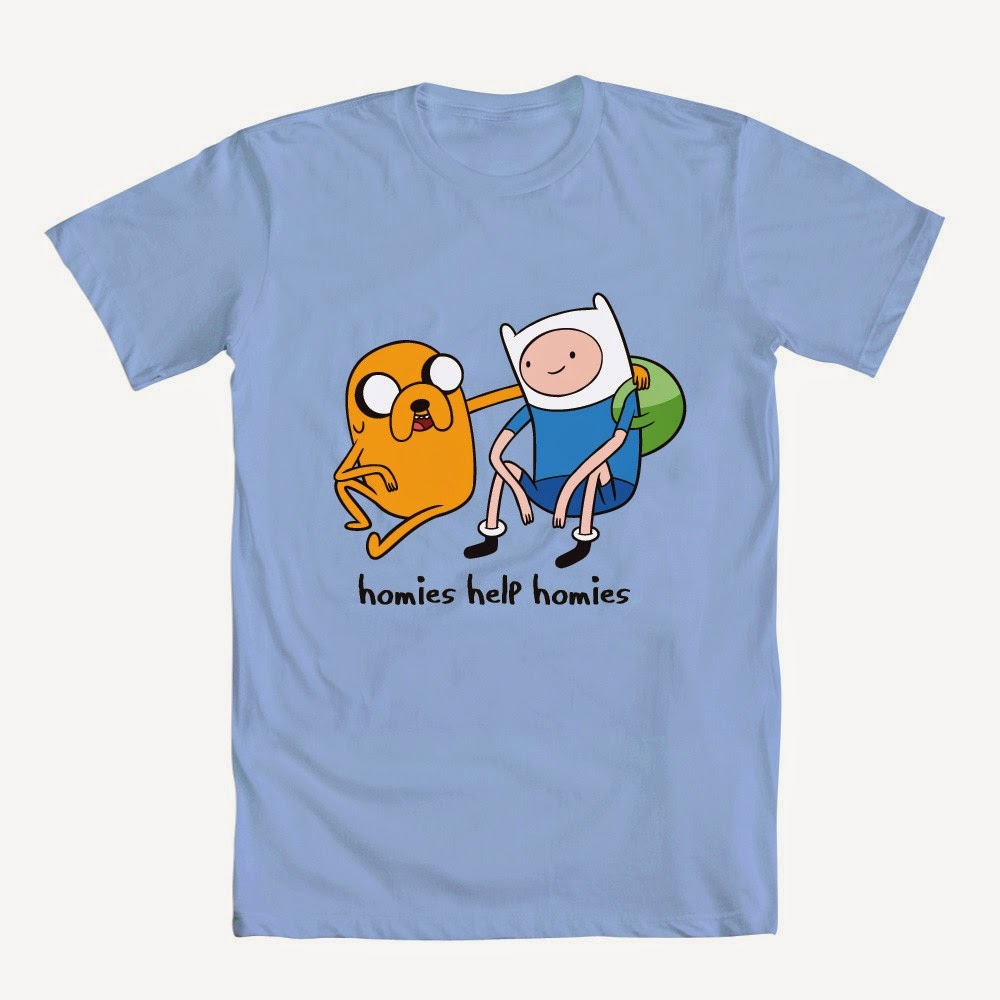
Homies Help Homies

As the above, tee-shirt quote says, "Homies help homies" (taken from the episode titled "Her Parents"). The idea of collaboration, of sharing wisdom and experience, is paramount for software development. As a newer developer, I can say that, through the wisdom of more senior developers, I have advanced at a rate beyond my ability to advance privately.

Lone-wolfing can be stunting. Through pair-programming, collaboration, mentoring and simply asking questions we benefit from the experiences of those who have seen more.

Programming Languages Are Like Jake's Favorite Cup


This is a pretty simple point: languages come and go. As developers, as stakeholders in an advancing industry, we need to be able to realize when a technology has expired. More importantly, we need to be able to move on and learn new technologies. There's nothing wrong with having a "favorite language" but, like Jake's cup, we need to be willing to drop it and learn something new, especially if our situation demands it.

Be Incremental


In the episode "Susan Strong," Finn and Jake meet Susan, one of many human-like beings that live underground. Upon bringing Susan to the world above, Finn recognizes that Susan is having trouble adjusting to her new environment. Finn decides to incrementally introduce the above-ground realm to Susan (this is when the above, modified Adventure Time logo is flashed).

This example of incremental exposure reminds me of two concepts that are important to developers, today. Firstly, when we learn new technologies, we should do so incrementally, so that we don't get overwhelmed. Secondly, when we develop software, it's helpful to do so incrementally. Incremental development is useful because it forces us to tackle small, bite-sized problems, resulting in bite-sized solutions that are more easily understood than complex, large solutions.

Saturday, March 15, 2014

Fluent Interfaces (With Ruby Examples)

As of late, a hammer of mine has been the use of fluent interfaces. Fluent interfaces are simply classes that, instead of having methods that return something uninteresting or nothing, return the calling instance.

So, in a general, strongly-typed language this might look like:
public class Foo {
    public Foo FluentMethod() {
        // do some stuff
        return this;
    }
}

For simplicity's sake, I will use Ruby for the rest of this post. In the Ruby language this would look more like:
class Foo
  def fluent_method()
    # do some stuff
    self
  end
end

One of the biggest benefits of fluent interfaces is that they make change easier. For example consider the following, non-fluent code:
a_chicken = Chicken.new

mr_fox = Fox.new
mr_fox.is_quite(:fantastic)
mr_fox.lives_in(:a_tree)
mr_fox.eat(a_chicken)

This code annoys me (somewhat) because mr_fox appears on four lines, which implies that if you wanted to change it, you would have to change each of the four lines. Also, if I fat-fingered one of those references, I would waste time fixing it when the interpreter caught it. Here comes fluent to the rescue:
a_chicken = Chicken.new

Fox.new
   .is_quite(:fantastic)
   .lives_in(:a_tree)
   .eat(a_chicken)

Isn't that better? mr_fox doesn't even exist anymore. Also, in my humble opinion, this style of method chaining greatly improves readability.

There's also a hidden benefit in this example: fluent interfaces logically group operations of a single object onto, technically, one SLOC. For example, if I didn't use fluent method chaining, there's nothing stopping me from mixing Chicken logic with Fox logic:
a_chicken = Chicken.new
mr_fox = Fox.new
mr_fox.is_quite(:fantastic)
a_chicken.is_named("rodrick")
mr_fox.lives_in(:a_tree)
a_chicken.still_has_its_head(true)
mr_fox.eat(a_chicken)

But if I made Fox fluent and described it with method chaining then there's no way for me to interleave Chicken logic, and, frankly, create a mess:
a_chicken = Chicken.new
a_chicken.is_named("rodrick")
a_chicken.still_has_its_head(:eggs)

Fox.new
   .is_quite(:fantastic)
   .lives_in(:a_tree)
   .eat(a_chicken)

Of course, I (at this point in my software career) would probably make Chicken fluent as well, but I think it's fairly clear what that would look like at this point.

Hopefully you've come to dig fluent interfaces (at least a little) at this point. To me it's pretty cool that (in dynamic languages) implementing a fluent interface can be as simple as tacking a four-letter-word (self) on the end of methods whose return value we found otherwise uninteresting.

Tuesday, January 28, 2014

7 Ways to Learn a New Programming Language

1. Read a Book

This is perhaps the most traditional approach. You have to be careful with this one, because in programming things evolve very quickly. If you are looking for some good, up-to-date books on languages, I would suggest The Pragmatic Bookshelf.

2. Watch YouTube Videos and Follow Along

There are an insane amount of YouTube tutorials out there. My main difficulty with learning programming on YouTube has always been finding reliable teachers. I generally trust GoogleTechTalks and TheNewBoston as go-tos.

3. Start a New Project

Simply learn by doing! It is probably best to do this after you have had some form of a primer on the language. This is one of the most effective ways I have learned new languages. Just think about what you want to build, open google and stackoverflow (keep them handy for language-specific questions) and start coding away!

4. Complete Koans

Koans (path to enlightenment) are a superb way to gain some understanding about a new programming language. Usually test driven, they make you fix small "errors" in code files that emphasize some little feature of the language. Koans are generally incremental so by solving them, a broader understanding of the language is gained.

5. Practice with Cyber-Dojo

This is another tool that you may want to use after you have had some primer on the language you are trying to learn. Cyber-dojo is a cool tool for practicing TDD. It isolates programmers from bloated IDEs so that they can focus on problems, code and tests. Cyber-dojo values finding solutions over the actual solution itself. This makes it a great resource for learning a language, purely from a "writing and testing code" perspective.

6.  (If you like Math) Practice with Project Euler

If you can't come up with projects to work on, ProjectEuler presents some fun mathematical challenges that (should) grow harder as you progress through the list of problems. It's fun to develop a code-base around ProjectEuler solutions.

7. (If you like Biology) Practice with Rosalind

Like ProjectEuler, Rosalid is a collection of programming-esque problems. Unlike ProjectEuler, Rosalind problems are centered around Biology. Very cool, and fun.

Extra Tips

  • Some languages have online, interactive teaching tutorials which can be cool to check out.
  • If an language has an REPL, it can be helpful to play around in it or keep it open as you develop (so you can try code as you think of it). The instant feedback of a REPL is priceless in learning.

Controversial Programming Opinions I Agree With

I recently came across Bill the Lizard's blog post about controversial programming opinions. Shockingly, some of these really threw me off guard. Others, however, I kind of agree with. I'm fairly new to this development thing, but I would still like to take my chance to chime in on some of these "controversial" opinions that I fully agree with.

5. "Googling it" is okay!

So, there's been a lot of debate about whether google is helping or hindering us. One of my favorite articles about google's psychological affects argues that we are becoming reliant on google for "mindshare" (the process of delegating memory tasks to people around us). Some people are disturbed by the idea that google could be "replacing our memory" but I see it as a good thing, and here's why:
  • If we didn't have google to quickly retrieve information for us, we would have to use some other form of reference (dictionary, textbooks) which are expensive, are not always available, and have a longer look-up time. Or maybe we would just neglect to pursue correct information altogether (let's face it, we're pretty lazy).
  • Consider the quotes: "I never commit to memory anything that can easily be looked up in a book" and "Never memorize what you can look up in books." (Einstein) and ask yourself, "does this apply to the opinion 5?"
  • There is too much information to store it all in your mind. I mean, don't get me wrong, there are plenty of things we should know as citizens and craftsmen in general, however, computer science is growing by the second. We can't know it all. Personally, I'm thankful that google knows things that I don't.

6. Not all programmers are created equal.

The gist of this one says that it's wrong to think that the amount of experience a developer has will indicate how good of a developer he (or she) is. I think Coding Horror has a few important points to make about this when he writes about becoming a better programmer, without programming.

7. I fail to understand why people think that Java is absolutely the best “first” programming language to be taught in universities.

Here's why I agree with this one:
  • Although OOP is a good thing to teach, universities (perhaps unfortunately) have to cater to a variety of majors, not just computer science. OOP is not necessary for many engineering students (e.g. electrical engineers who program chips in C and Assembly).
  • Java is difficult to "ease into." Intro to programming classes are just that, an intro. They should illustrate basic concepts. Java has a lot of overhead. For example, in Java, the classic "Hello, World" program has overhead that teachers, upon first exposure to students, are forced to wave their hands at. Right off the bat students are told to "just ignore 80% of what they're typing, just to make the computer say hello." Whereas, in simple languages like Python and Ruby, "Hello, World" can be as simple as a print statement and a string, two simple intro concepts that are isolated and less distracting than embedded classes.
  • For more advanced classes, a language like Java may be appropriate; however, there is a lot of speculation going around that Java is on the decline in the industry. The point is, even if it is the current, best language to teach -- it won't always be. It will die.
  • Java is a great language for teaching OOP, I'll give it that. But it fails to illustrate certain, slightly advanced, fundamental programming concepts (that schools like to teach) like pointers, manual memory allocation, etc... So even for advanced classes it isn't capable of teaching some slightly more advanced concepts.
  • I am, personally, fine with schools using Java, it is a good language. The statement that "it is absolutely the best" is flawed in that, it's just one of many excellent programming languages. To anyone who thinks otherwise, I would highly suggest Guido's PyCon keynote in which he criticizes language holy wars and trolls.

9. It’s OK to write garbage code once in a while.

  • It's better to write quick garbage code that does the job and later refactor it than it is to be an Artist.
  • Proof of Concept (POC) code is just proving a point. It doesn't necessarily need to be later maintained, read or extended.
  • Writing crappy code is part of learning to write better code. Also, refactoring your bad code can help you learn how to refactor others' bad code.

18. If you’re a developer, you should be able to write code.

Assuming "developer" means "one who constructs software" it seems necessary to be able to "stack the legos." Similarly to you can't break an omelette without breaking some eggs, you can't construct software without writing some code.

There are the opinions I find myself pretty much for. Please feel free to disagree in comments and let my know what you think.

Tuesday, April 23, 2013

Determinant in Haskell

In linear algebra, the determinant is quite a useful operation that can be done on matrices. To further my understanding of Haskell, I decided to program a solver for systems of equations. One of the best ways to do this dynamically is through Cramer's Rule which needs to be able to calculate determinants. So, here's my recursive code for finding determinants:

determinant :: (Num a, Fractional a) => [[a]] -> a

determinant [[x]] = x
determinant mat =
 sum [(-1)^i*x*(determinant (getRest i mat)) | (i, x) <- zip [0..] (head mat)]


So, in this code, the base case is a 1x1 matrix. The getRest function simply returns the matrix without the head row (topmost) and without the \(i\)th column.

The code and tests are available on my github.